Who Bears the Cost When NumPy Changes?

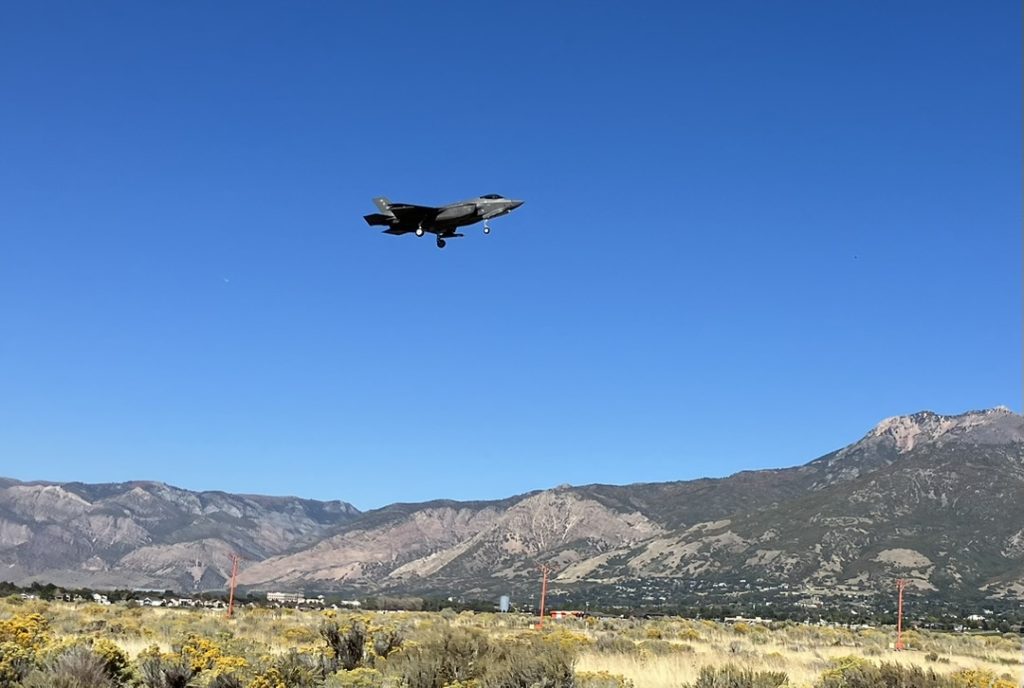
I’m teaching Python to scientists and engineers at Hill Air Force Base this week. Yesterday, after class, I spent some time plane-spotting—one of the occupational benefits of teaching on an Air Force base. While aircraft were coming and going, I was thinking about something considerably less interesting: a NumPy deprecation warning that popped up during class.
I had written something utterly ordinary:

a.shape = (m, n)

And NumPy warned me that direct assignment to an array’s shape is deprecated.

DeprecationWarning: Setting the shape on a NumPy array has been deprecated in NumPy 2.5.
As an alternative, you can create a new view using np.reshape (with copy=False if needed).

Wait, what??! I don’t want a new view; I want to mutate the array I already have!

I’ve been teaching NumPy for a long time—well over 100 classes, to something like 1,500 students. I’ve seen plenty of APIs come and go; Pandas, in particular, has periodically made me grumble as useful idioms disappeared while the library matured.

But NumPy? NumPy has generally been the stable foundation underneath all of that. Assigning to .shape isn’t some obscure corner of its API. It fits beautifully into both Python’s object model and the mental model I’ve taught for years.

What’s wrong with changing an array’s shape?

Python names are like sticky notes attached to objects:

>>> x = [1, 2, 3]
>>> y = x
>>> y[1] = -9
>>> x
[1, -9, 3]
>>> y is x
True

x and y refer to the same list. Mutate the list through y, and the change is visible through x.

That’s not a bug, that’s Python’s “dynamic typing” that enables everything from for loops to import aliases.

NumPy arrays have traditionally behaved exactly as I’d expect:

>>> a = np.arange(12)
>>> b = a
>>> a.shape = (3, 4)
>>> b.shape
(3, 4)

There is one array object. Both names refer to it. I changed its shape, so naturally b.shape is now (3, 4) too.

More importantly, that’s a wonderfully simple thing to explain to a scientist learning NumPy:

Here is some numerical data. The shape describes how NumPy interprets it. If the storage permits it, you can change that shape.

There’s quite a lot of useful understanding packed into that little example.

But evidently, that’s deprecated now, and the preferred approach is this:

a = a.reshape(3, 4)

Usually that doesn’t copy the underlying data. But it does create a new Python ndarray object—a new view onto the same storage, which is not the same operation. In the code above, a ends up with a new identity.

Sometimes I really do mean: mutate this object.

So why take that away?

The answer, it would seem, is Concurrency, bane of Python developers since the early days. (I’m thinking in particular of one former co-worker; usually even-keeled, I only ever heard him swear once, and it was related to asyncio [warning: here be dragons])

More specifically, NumPy is adapting to a world of free-threaded Python and increasingly concurrent numerical computation. If multiple threads can operate on the same array, allowing one thread to change structural metadata such as shape and strides underneath another creates some nasty possibilities. And that’s a legitimate engineering problem.

But my immediate reaction was: why is that my problem?

Or, more importantly, why does it have to be my students’ problem?

The scientists and engineers I teach generally aren’t building highly concurrent numerical infrastructure. They’re using Python to solve engineering problems, analyze experimental results, process measurements, build models, and understand their work because Python is supposed to be easy to learn.

If they’ve created an array and want to mutate its shape, this seems like a perfectly reasonable contract:

You asked to mutate the array. NumPy will mutate it. If something else has a reference to the same object, it will see the mutation. Don’t do this concurrently unless you know what you’re doing.

That’s pretty much how mutable Python objects have always worked.

Haven’t we already invented tensors?

This is where I start getting cranky.

NumPy was created as a pragmatic numerical tool for scientists and engineers (read about it here). Since then we’ve developed PyTorch, TensorFlow, JAX, CuPy, and an increasingly sophisticated ecosystem of tensor and array systems.

Those systems have requirements NumPy didn’t originally have: GPUs, asynchronous execution, automatic differentiation, computation graphs, accelerators, massive parallelism, and so forth.

And that’s fine. In fact, it reminds me of something the IPython project did very well.

At some point, IPython was becoming much more than an interactive Python shell. The notebook architecture had implications well beyond Python. Rather than continuing to stretch “IPython” until it meant everything (and therefore nothing), the project created Jupyter.

IPython remained IPython, and the more general abstraction got its own identity. It kept its clean conceptual boundary.

So why can’t NumPy concede some of these requirements to the tensor world?

Let PyTorch tensors make whatever concurrency concessions PyTorch needs. Let TensorFlow tensors behave however TensorFlow needs them to behave. Let JAX arrays have the semantics necessary for JAX.

And let a NumPy array remain the wonderfully pragmatic numerical object that made Python attractive to the scientists and engineers I serve in the first place.

Of course it’s not actually that simple. NumPy itself is used concurrently, and the modern numerical Python ecosystem benefits enormously from interoperability among all of these array systems.

But notice what happens when we solve that ecosystem-level problem by changing NumPy.

Who bears the cost?

That’s the question I’ve been circling around.

Making NumPy easier to use as a foundation for a concurrent array ecosystem reduces complexity for framework and library developers.

But the complexity doesn’t simply disappear — it has to go somewhere. In fact, some of it gets transferred. To me. To my students. Early in their learning process when they’re already juggling a lot of new concepts.

Now I have to change an explanation I’ve used in many dozens of classes. My students have to learn that although many Python objects are mutable, and although an ndarray‘s numerical contents are mutable, its structural interpretation is increasingly something they should regard differently.

Instead of:

a.shape = (3, 4)

I teach:

a = a.reshape(3, 4)

A student asks, “Does that create another array?”, and the answer is yes, another ndarray object, although it no longer “owns” its own data and it may or may not copy the underlying data. That leads to a discussion on views, storage, object identity, aliasing, and maybe why changing structural metadata creates problems under concurrency.

These are all interesting topics, but none of them is what the engineer was trying to learn at that moment, and that’s the cost that bothers me. It’s not the keystrokes, it’s cognitive load.

I often introduce Python by talking about the tradeoffs between design time, run time, and debug time and how Python has traditionally prioritized design time (easy to write code, linear learning curve), and debug time (Python makes it easy to write code that is easy to debug, if you know what you’re doing). Performance can come later, with more time and effort. For decades, one of Python’s great strengths in scientific computing has been that the machinery gets out of the way quickly enough that a domain expert can concentrate on the domain.

Increasingly, Python is also infrastructure for enormous software systems—AI frameworks among them. Those systems need stronger invariants, concurrency, static analysis, interoperability, and carefully specified behavior across layers of software that no single programmer can understand completely.

Those are legitimate needs, but they’re not free, and sometimes (often) the cost is paid by the scientist sitting at a prompt who now has one more abstraction to understand before getting back to the actual problem.

And sometimes it’s paid by the instructor standing in front of that scientist, surprised by yet another deprecation warning and deciding whether today’s lesson really needs a digression into free-threaded Python just to explain why changing the shape of an array isn’t supposed to work that way anymore.

Yesterday, watching an F-5 and an F-35 land after class, an analogy came to me. The F-5 first flew in 1959, and it is still useful in 2026—not because it accumulated every mission and every capability, but because it has remained very good at a narrower job.
At Hill, that job is helping F-35 pilots train against a realistic adversary. It can serve the newer system without becoming the newer system. It can adapt to a new environment without giving up its core identity.

Of course I understand that software projects are not airplanes (although you could argue that airplanes are increasingly becoming software projects), and NumPy cannot simply ignore concurrency. But usefulness and maximal generality are not the same thing. As a project accumulates new constituencies and new requirements, the technically clean solution for the larger ecosystem can impose costs on the people for whom the tool was originally built.

Those costs are easy to dismiss individually: a deprecation warning here, a slightly different idiom there, one additional concept to explain.

But, as I frequently say in my classes, cognitive load accumulates. And for scientific software in particular, the cognitive load of the tool competes directly with the cognitive load of the science.

When we change the tools, it’s worth asking not only whether the new design is cleaner or safer.

It’s worth asking who bears the cost.

“Protecting the Training Period”

I recently finished reading Nobel-laureate Daniel Kahneman’s “Thinking, Fast and Slow” and found it to to be thought-provoking and more than a little humbling in light of the current generative AI revolution and the role of cognitive effort in learning. From the notion of System 1 and System 2 (about which I’ve written before) to the value of formulas over intuition (linear models!), and the efficiency-seeking (a.k.a laziness) of the human brain when it comes to cognitive tasks, the book articulates many of the principles that guide us at Diller Digital and that Enthought used for training many years previously.

Cover of Daniel Kahneman's book "Thinking, Fast and Slow", which contains important ideas about the role of cognitive effort.

One of the most important takeaways for me is that in educational environments, one must carefully manage cognitive effort. In the age of LLMs, I increasingly see the role of an instructor like that of a sherpa, guiding students to the most productive use of cognitive effort during a focused period, and avoiding wasted effort on trivialities that don’t contribute to long-term success. This is particularly the case with students in mid-career, who have limited blocks of time for training, and whose other demands don’t all magically disappear during a week of training.

Among the humbling insights from the book was that the way System 1 & System 2 work, coupled with our blind spots (“What You See Is All There Is”), can lead us into poor decision making. This plays out in many ways, of course, but I’m thinking in particular of those captains of industry who assure us that we can stop writing code now. Sam Altman recently felt a little useless, which was sad, that ChatGPT had come up with a better idea than him, for example. I was dismayed by how easily he seemed to give up his sense of worth or to measure his value by productivity.

So my attention was caught by “Betting blind on AI and the scientific mind“, an article by Tim Requarth, a professor at NYU, who was struggling, as many educators do these days, with the question of AI’s use in the classroom. On one hand, there are those who assert that AI causes brain rot — skill atrophy in the presence of automation is a well documented phenomenon. This side takes as a banner the statement “writing is thinking” and points to the likes of Richard Feynman and his laboratory notebooks as evidence that there are no shortcuts around cognitive effort. And on the other side are the AI evangelists who glibly point out how much they were able to accomplish with the aid of an LLM, assert that prompt engineering and human-based discussions are just as legitimate forms of thinking as writing, and wonder who cares about the details of APIs anyway? What’s missed in these glib statements is the importance of cognitive effort for training. Both the AI-reactionary and AI-evangelist voices have valid points to make, but they are too often presented in extreme. We’ll try to keep the middle ground here.

Given that we generally agree on the importance of cognitive effort for learning (see Derek Muller’s “Effort Is the Algorithm” for a fun take), a pair of assertions Pf. Requarth made intrigued me. First, and this is very much in line with Kahneman’s decision-making traps, we are very bad at perceiving and judging our own cognitive state. Said another way, thinking hard hurts, and we don’t like pain, so it’s very difficult for us to differentiate beneficial cognitive effort from tedium.

Second, and this follows directly from the first, “any tool that preserves productive struggle will probably lose in the marketplace to tools that eliminate it.” This is the tricky piece – because our brains tend not to like effortful thinking, we instinctively avoid it.

Any tool that preserves productive struggle will probably lose in the marketplace to tools that eliminate it.

The solution to the conundrum is to recognize and curate the training experience. In an academic setting, this means banning the use of LLMs to aid in writing doctoral research proposals and dissertations, or essays in middle or high school. Or in continuing education like Diller Digital provides, it means taking the time to work through the fundamentals, and spending the cognitive effort — at least once — to learn how a list differs from a tuple or a Numpy ndarray and why it matters in scientific computing. In my years as a consultant for Enthought, for example, I saw many managers go through our training and emerge with understanding that greatly enhanced their leadership of technical projects, even though they never wrote another line of code after completing the class. A well-trained individual can exercise discernment about whether to employ a tool, because not every email or every piece of shim code needs a human’s full attention. But if they choose to use the tool, it will not be because they didn’t have the skill, or it was too cognitively painful for them to do it themselves.

Ultimately, I agree with Requarth’s recommendation to “use AI responsibly” by protecting the training period, managing the “friction” of the tools, and speaking about use of LLMs and other “AI” technology with nuance.

On Software Craftsmanship

Last week I found myself engaged with a group of students from Los Alamos National Laboratories in our Software Engineering for Scientists & Engineers, known informally as Software Craftsmanship. Apart from the epic New Mexico skies, the grand vistas, and the welcome relief from the heat and humidity of my hometown Austin, what I particularly loved about the week was the focus on craftsmanship.

This class had a high proportion of people I’d worked with before learning Python programming, data analysis, and/or machine learning, so it was easy to build rapport. Questions and dialog flowed easily. One student had this to say:

The interactivity of the in-person class, paired with the detailed course slides, was very effective. The source control (git), readable code, refactoring, and unit testing sections were all very useful and will be directly impactful to my work. There were multiple instances throughout the week where I learned something that would have saved me significant time on a problem I had encountered within the last 6 months.

One of the things we cover in the class is code review, the practice of submitting your code for review and critique before it’s accepted into a project, in some ways similar to the academic peer-review process. At Diller Digital, we try model this process by submitting and responding to feedback on the course materials. In response to a session of Software Engineering earlier this year, students suggested we learn source control and the details of git at the start of the class and then use it in a workflow typical of small teams in an R&D environment. Diller Digital has a git server (powered by Gitea, a close analog to GitHub and GitLab), and we created a class repository and developed a couple of small libraries that can serve as best-practice examples of variable naming, use of the logging library, Sphinx-ready documentation, unit testing, and packaging using standard tooling. One of the many jokes about git is that you can learn how to do 90% of what you’ll need with only understanding 10% of what’s actually going on. I’m not sure about the numbers there, but I do know that using and practicing what you’ve learned makes all the difference.

The in-person, instructor-led format makes engagement much easier and lowers the barriers to asking questions and providing individualized help. But one of the important principals behind that is the role of effortful thinking in learning. I like the way Derek Muller (of Veritasium fame) explains in this video how we have two systems in our brain, one fast — for instinctive, rapid-fire processing of the kind you’re using to parse the words on this page, and one slow – the effortful, brain-taxing system required for understanding something.

It’s probably that effortful system you’re using trying to understand my point, and you’ll surely use it trying to tell whether 437 is evenly divisible by 7 in your head. It’s not quite as simple as two distinct systems, as the author of that idea, Daniel Kahneman, makes clear in his book, Thinking, Fast and Slow, but it gives us a useful mental model for talking about software craftsmanship, and why we teach the way we do at Diller Digital. One of the main takeaway points is that effortful thinking is necessary for learning, but not all effortful thinking results in useful learning.

One of the first ideas we introduce in Software Engineering is that of cognitive load and its management. Cognitive load is a measure of effortful thinking — it’s the effort required to understand something, and we would like that effort to be spent on important things like the business logic of an algorithm and not on trivial things like indentation and syntax. That’s the purpose using a coding standard — once your brain gets used to seeing code that’s formatted in a common way (for Python it’s embodied in PEP8), the syntax becomes transparent (it’s handed off to the fast thinking part of our brain), and you can see through it to the logic of the code and spend your effort understanding that. Code that’s not formatted that way introduces a small cognitive tax on each line that adds up to measurable fatigue over time. If you want an example of that kind of fatigue, try this little game.

So managing cognitive load informs choices of layout, use of white space, and selecting the names of Python objects, and this is one of the important things we teach in Software Engineering. But it also informs the way we design our courses. We introduce ideas and demonstrate them and then have our students spend effort internalizing them, first in a simple “Give It A Try” exercise and eventually in a comprehensive exercise. The goal is to direct our students’ effort to increasingly independent tasks, in what is sometimes called a “fading scaffold”, where early effort is guided closely, and in later efforts, students have more room to make and recover from mistakes. This is also the thinking behind the presence in some courses of “Live Coding” scripts, where demos and exercises are set up already, and the student only has to focus on the learning goal and not on typing all of the supporting code around it. These have proven to be especially popular in our Machine Learning and Deep Learning classes.

This also suggests a strategy for the effective use of Large Language Models for coding. Use them reduce effort where it’s not critical to gain understanding or to gain a skill. But don’t let them replace effortful thinking where it counts most — in learning and in crafting your scientific, engineering, or other analytical workflow. And if you want a guide in your learning journey, we’re here to help. Click here for the course schedule.

I have taken four courses with Diller Digital and this [Software Engineering] is by far the most useful one. Many of us have learned programming as a need to do research, but we do not have any formal background in computational programming. I think this course takes basic Python programming skills to a more formal level, aligned with people with programming background allowing us to improve the quality of code we produce, the efficiency in the implementation and collaboration. 
Also, hosting the course in person made a big difference for me. I was easily engaged the entire day, the exercises and the possibility to ask in person made the entire course smoother.

I think this course material is incredibly helpful for people who don’t have professional software engineering experience. Of all the courses I took from Diller Digital, I found this the most foundational and immediately useful.

“Popping the Hood” in Python

One man holds the hood of a car open while he and his friend look at the engine together.

Last weekend found me elbow-deep in the guts of my car, re-aligning the timing chain after replacing a cam sprocket. As I reflected on the joys of working on a car with only 4 cylinders and a relatively spacious engine bay, I found myself reflecting on one of the things I love best about the Python programming language — that is the ability to proverbially “pop the hood” and see what’s going on behind the abstractions. (With a background in Mechanical Engineering, car metaphors come naturally to me.)

As an Open Source, well-documented, scripted language, Python is already accessible. But there are some tools that let you get pretty deeply into the inner workings in case you want to understand how things work or to optimize performance.

Use the Source!

The first and easiest way to see what’s going on is to look at the inline help using Python’s built-in help() function, which displays the docstring using a pager. But I almost always prefer using the ? and ?? in IPython or Jupyter to display the just the docstring or all of the source code if available. For example consider the relatively simple parseaddr function from email.utils:

In [1]: import email

In [2]: email.utils.parseaddr?
Signature: parseaddr(addr, *, strict=True)
Docstring:
Parse addr into its constituent realname and email address parts.

Return a tuple of realname and email address, unless the parse fails, in
which case return a 2-tuple of ('', '').

If strict is True, use a strict parser which rejects malformed inputs.
File:      /Library/Frameworks/Python.framework/Versions/3.13/lib/python3.13/email/utils.py
Type:      function

In our Python Foundations course, I can usually elicit some groans by encouraging my students to “Use the Source” with the ?? syntax, which displays the source code, if available:

In [3]: email.utils.parseaddr??
Signature: parseaddr(addr, *, strict=True)
Source:   
def parseaddr(addr, *, strict=True):
    """
    Parse addr into its constituent realname and email address parts.

    Return a tuple of realname and email address, unless the parse fails, in
    which case return a 2-tuple of ('', '').

    If strict is True, use a strict parser which rejects malformed inputs.
    """
    if not strict:
        addrs = _AddressList(addr).addresslist
        if not addrs:
            return ('', '')
        return addrs[0]

    if isinstance(addr, list):
        addr = addr[0]

    if not isinstance(addr, str):
        return ('', '')

    addr = _pre_parse_validation([addr])[0]
    addrs = _post_parse_validation(_AddressList(addr).addresslist)

    if not addrs or len(addrs) > 1:
        return ('', '')

    return addrs[0]
File:      /Library/Frameworks/Python.framework/Versions/3.13/lib/python3.13/email/utils.py
Type:      function

Looking at the next-to-last line, you see there’s a path to the source code. That’s available programmatically in the module‘s .__file__ attribute, so you could open and print the contents if you want. If we do that for Python’s this module, we can expose a fun little Easter Egg.

In [4]: import this
# <output snipped - but try it for yourself and see what's there.>

In [5]: with open(this.__file__, 'r') as f:
   ...:     print(f.read())
   ...: 
s = """Gur Mra bs Clguba, ol Gvz Crgref

Ornhgvshy vf orggre guna htyl.
Rkcyvpvg vf orggre guna vzcyvpvg.
Fvzcyr vf orggre guna pbzcyrk.
Pbzcyrk vf orggre guna pbzcyvpngrq.
Syng vf orggre guna arfgrq.
Fcnefr vf orggre guna qrafr.
Ernqnovyvgl pbhagf.
Fcrpvny pnfrf nera'g fcrpvny rabhtu gb oernx gur ehyrf.
Nygubhtu cenpgvpnyvgl orngf chevgl.
Reebef fubhyq arire cnff fvyragyl.
Hayrff rkcyvpvgyl fvyraprq.
Va gur snpr bs nzovthvgl, ershfr gur grzcgngvba gb thrff.
Gurer fubhyq or bar-- naq cersrenoyl bayl bar --boivbhf jnl gb qb vg.
Nygubhtu gung jnl znl abg or boivbhf ng svefg hayrff lbh'er Qhgpu.
Abj vf orggre guna arire.
Nygubhtu arire vf bsgra orggre guna *evtug* abj.
Vs gur vzcyrzragngvba vf uneq gb rkcynva, vg'f n onq vqrn.
Vs gur vzcyrzragngvba vf rnfl gb rkcynva, vg znl or n tbbq vqrn.
Anzrfcnprf ner bar ubaxvat terng vqrn -- yrg'f qb zber bs gubfr!"""

d = {}
for c in (65, 97):
    for i in range(26):
        d[chr(i+c)] = chr((i+13) % 26 + c)

print("".join([d.get(c, c) for c in s]))

Another way to do this is to use the inspect module from Python’s standard library. Among many other useful functions is getsource which returns the source code:

In [6]: import inspect
In [7]: my_source_code_text = inspect.getsource(email.utils.parseaddr)

This works for libraries and functions that are written in Python, but there is a class of functions that are implemented in C (for the most popular version of Python, known as CPython) and called builtins. Source code is not available for those in the same way. The len function is an example:

In [8]: len??
Signature: len(obj, /)
Docstring: Return the number of items in a container.
Type:      builtin_function_or_method

For these functions, it takes a little more digging, but this is Open Source Software, so you can go to the Python source code on Github, and look in the module containing the builtins (called bltinmodule.c). Each of the builtin functions is defined there with the prefix builtin_, and the source code for len is at line 1866 (at least in Feb 2025 when I wrote this):

static PyObject *
builtin_len(PyObject *module, PyObject *obj)
/*[clinic end generated code: output=fa7a270d314dfb6c input=bc55598da9e9c9b5]*/
{
    Py_ssize_t res;

    res = PyObject_Size(obj);
    if (res < 0) {
        assert(PyErr_Occurred());
        return NULL;
    }
    return PyLong_FromSsize_t(res);
}

There you can see that most of the work is done by another function PyObject_Size(), but you get the idea, and now you know where to look.

Step by Step

To watch the Python interpreter step through the code a line at a time and explore code execution, you can use the Python Debugger pdb, or its tab-completed and syntax-colored cousin ipdb. These allow you to interact with the code as it runs and execute arbitrary code in the context of any frame of execution, including printing out the value of variables. They are the basis for most of the Python debuggers built in to IDEs like Spyder, PyCharm, or VS Code. Since they are best demonstrated live, and since we walk through their use in our Software Engineering for Scientists & Engineers class, I’ll leave it at that.

Inside the Engine

Like Java and Ruby, Python runs in a virtual machine, commonly known as the “Interpreter” or “runtime”. So in contrast to compiling code in, say, C, where the result is an executable object file consisting of system- and machine-level instructions that can be run as an application by your operating system, when you execute a script in Python, your code gets turned into bytecode. Bytecode is a set of instructions for the Python virtual machine. It’s what we would write if we were truly writing for the computer (see my comments on why you still need to learn programming).

But while it’s written for the virtual machine, it’s not entirely opaque, and it can sometimes be instructive to take a look. In my car metaphor, this is a bit like removing the valve cover and checking the timing marks inside. Usually we don’t have to worry about it, but it can be interesting to see what’s going on there, as I learned when producing and answer for a Stack Overflow question.

In the example below, we make a simple function add. The bytecode is visible in the add.__code__.co_code attribute, and we can disassemble it using the dis library and turn the bytecode into something slightly more friendly for human eyes:

In [9]: import dis
In [10]: def add(x, y):
    ...:     return x + y
    ...: 
In [11]: add.__code__.co_code
Out[11]: b'\x95\x00X\x01-\x00\x00\x00$\x00'
In [12]: dis.disassemble(add.__code__)
  1           RESUME                   0

  2           LOAD_FAST_LOAD_FAST      1 (x, y)
              BINARY_OP                0 (+)
              RETURN_VALUE

In the output of disassemble, the number in the first column is the line number in the source code. The middle column shows the bytecode instruction (see the docs for their meaning), and the right-hand side shows the arguments. For example in line 2, LOAD_FAST_LOAD_FAST pushes references to x and y to the stack, and the next line BINARY_OP executes the + operation on them.

Incidentally, if you’ve ever noticed files with the .pyc extension or folders called __pycache__ (which are full of .pyc files) in your project directory, that’s where Python stores (or caches) bytecode when a module is imported so that next time, the import is faster.

In Conclusion

There’s obviously a lot more to say about bytecodes, the execution stack, the memory heap, etc. But my goal here is not so much to give a lesson in computer science as to give an appreciation for the accessibility of the Python language to curious users. Much as I think it’s valuable to be able to pop the hood on your car and point to the engine, the oil dipstick, the brake fluid reservoir, and the air filter, I believe it’s valuable to understand some of what’s going on “under the hood” of the Python code you may be using for data analysis or other kinds of scientific computing.